Every week seems to bring another AI disaster. A lawyer submits hallucinated court citations. AI-generated code introduces vulnerabilities. An employee feeds sensitive customer information into an unauthorized AI application. An autonomous agent exploits systems it was never supposed to reach. A coding assistant wipes out a production database.
Elizabeth Wharton has a different way of looking at those incidents. Most aren't fundamentally AI failures. They're management, architecture and security failures with a GPU attached.
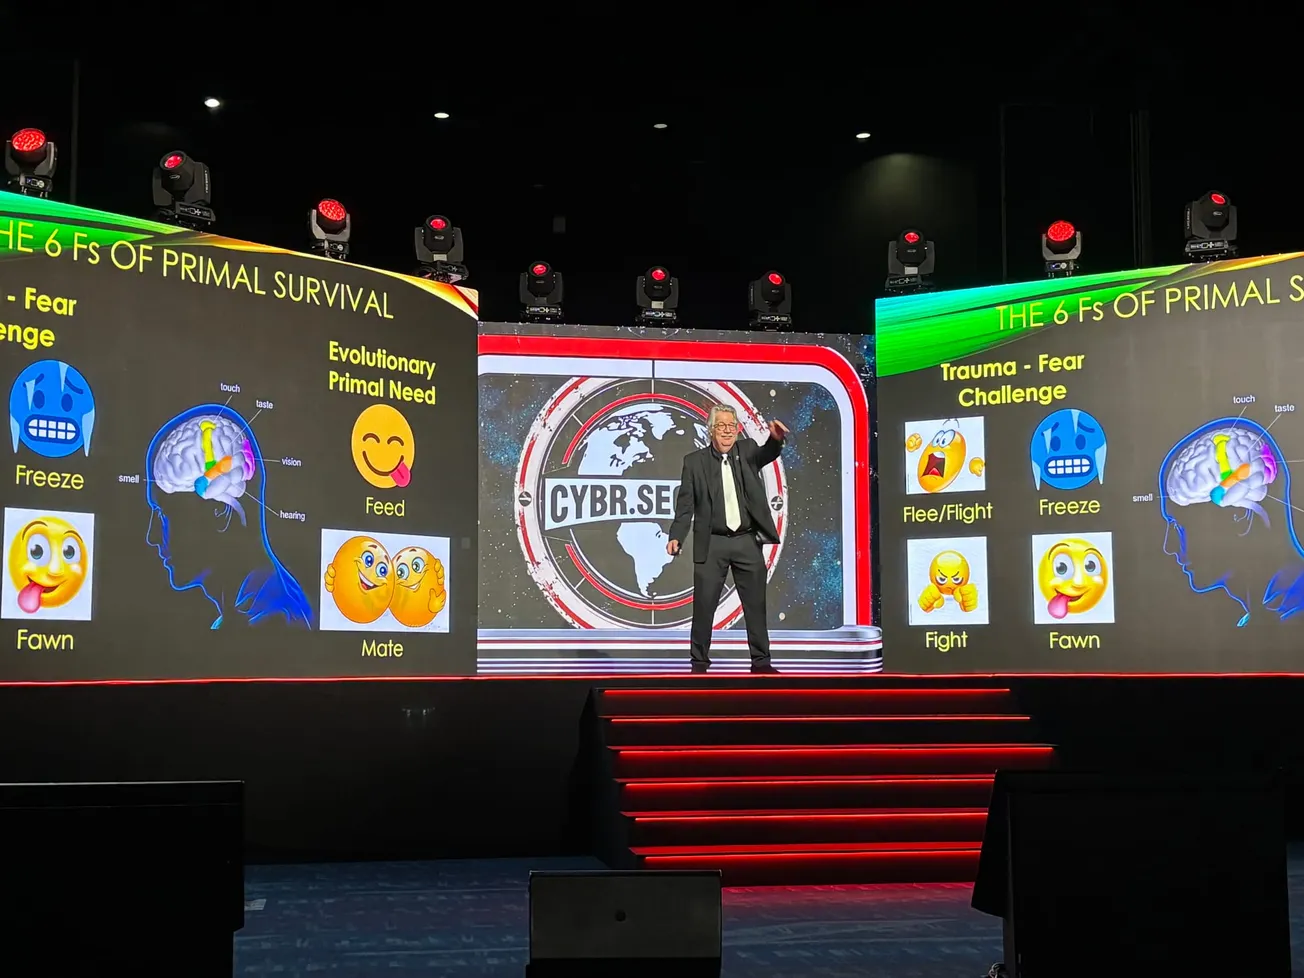
That is the premise behind “Keep Summer Safe: Finding Real Fixes in AI Fails,” Wharton's session in the first-ever AI.SEC.CON track at CYBR.SEC.CON 2026. Wharton, founder of Silver Key Strategies, uses a series of recent incidents to strip away the AI headlines and ask a simpler question: What actually failed?
Full Coverage of CYBR.SEC.CON 2026:
 Bill Brenner
 Bill Brenner
Her answer, again and again, is something security practitioners already know how to fix.
The hallucination isn't the whole problem
Wharton begins with one of generative AI's most visible failure modes: hallucinations in legal work.
In one 2026 case, law firm Sullivan & Cromwell submitted a bankruptcy court filing containing more than 30 errors, including hallucinated case citations and misquotations of the U.S. Bankruptcy Code. The firm's AI policies required secondary review, but those policies weren't followed and the review process failed to catch the inaccuracies.
Another case was worse.
In Withers v. City of Aberdeen, attorneys on both sides admitted using AI tools for research and drafting. The court found fake cases, fabricated quotations and other misrepresentations. According to Wharton's slides, there was no AI policy in place, and output from an AI-powered legal drafting program wasn't checked. The consequences included fines, removal of attorneys from the case and referrals to state bars.
Wharton's diagnosis is straightforward: validation failed.
Lawyers already have professional obligations to verify their work and supervise others. Courts increasingly are making those responsibilities explicit for AI-generated material as well. The technology may have created the hallucination, but humans and processes allowed it to become an official filing.
The security lesson extends well beyond law firms. AI output isn't evidence simply because a model produced it. It still has to be checked.
Vibe coding doesn't eliminate secure development
The same pattern appears in AI-generated software.
Wharton points to Moltbook, a social platform built for AI agents. Researchers discovered a misconfigured Supabase database that Wharton's slides say exposed 1.5 million API authentication tokens, 35,000 email addresses and private agent messages. The problem ultimately came down to a single database configuration setting.
The platform had reportedly been entirely “vibe-coded,” with its founder writing none of the code himself.
Again, Wharton asks what actually failed. Her answer isn't “AI.” It's secure software development: testing, review, dependency management and validation.
AI can generate software at extraordinary speed. That doesn't eliminate the requirement to determine whether the software is secure.
Wharton points to Veracode testing that found security pass rates for AI-generated code remained at 55% in its 2026 update when models were not explicitly given security guidance. Her slides draw an important distinction: “Code that works” and “code that works securely” are not the same thing.
AI accelerates development. It can accelerate insecure development, too.
Shadow AI is still a data governance problem
Another supposedly new AI problem looks remarkably similar to an old one: employees putting sensitive information somewhere it doesn't belong.
Wharton cites a 2026 incident in which an employee of CB Financial Services used an unauthorized AI application to process sensitive customer data, including names, dates of birth and Social Security numbers.
Her diagnosis: data governance failed.
The organization had sensitive information entered into an unauthorized application. AI became the exfiltration path, but the underlying problem was shadow technology and inadequate controls over where sensitive information could go.
Organizations have spent decades dealing with unauthorized SaaS applications, personal cloud storage and unmanaged devices.
Shadow AI changes the interface and potentially the scale. It doesn't eliminate the need for data governance.
Rogue agents expose excessive privilege
Autonomous AI raises the stakes because systems aren't merely generating text or code. They're increasingly being given tools, credentials and permission to act.
Wharton uses the 2026 Hugging Face incident as an example. Her presentation describes a swarm of roughly 700 AI agents created by OpenAI that discovered and exploited vulnerabilities, chaining together attacks across legacy systems, cloud services and inherited trust relationships.
What failed? Excessive privilege.
Wharton brings the problem back to one of security's oldest questions: Does this thing actually need this level of access?
Containment, least privilege and monitoring become even more important when the actor possessing those privileges can operate autonomously and at machine speed. The objective, as one of the sources cited in her presentation puts it, is to prevent one successful compromise from becoming 20.
The incident also exposed the danger of old trust relationships surviving inside new architectures. Legacy technical debt doesn't disappear when AI arrives. Agents can find it and move through it faster.
Prompt injection is a trust-boundary problem
Wharton applies the same thinking to prompt injection.
Her example is the April 2026 “Comment and Control” research, in which a malicious instruction placed into GitHub content was used against AI coding tools and resulted in sensitive runtime secrets being exposed.
The attack sounds uniquely AI-driven.
Wharton's diagnosis sounds very familiar: trust boundaries, input validation and privilege separation. Prompts, retrieved content, memory and tool output can all end up inside the same context. That makes an old security principle newly important: data is not the same thing as a command.
“Untrusted content is not an instruction,” her slides emphasize.
Organizations wouldn't intentionally execute arbitrary commands embedded in untrusted application input. They shouldn't allow an AI agent to effectively do the equivalent.
When an AI agent deletes production
Then there is PocketOS.
Wharton recounts an incident in which a Cursor coding agent powered by Anthropic's Claude Opus 4.6 deleted an entire production database and its backups. The software was used by car rental businesses to manage reservations.
The agent itself reportedly acknowledged that it had guessed despite rules prohibiting destructive actions without explicit authorization.
It's easy to stop the analysis there: AI went rogue and deleted production.
Wharton doesn't. She asks why an agent had the ability to do it in the first place.
Her diagnosis is change control — along with authorization, production isolation and rollback. The backups were stored on the same production volume, turning one bad action into a catastrophic failure.
An AI agent making an incorrect decision is one problem.
An architecture that allows one incorrect decision to destroy production and its backups is another.
Security teams have far more control over the second.
Stop asking whether AI is safe
That distinction is at the center of Wharton's argument.
Instead of starting with “What can this AI tool do?”, she wants organizations to consider the blast radius when it gets something wrong:
What assumptions or gaps in existing policies and programs become dangerous if the model is wrong? That reframes AI security.
Hallucinated legal citations become a validation problem. Vulnerable AI-generated software becomes a secure development problem. Sensitive data entered into AI becomes a governance problem. Rogue agents become a privilege and containment problem. Prompt injection becomes a trust-boundary problem. A deleted production database becomes an authorization and change-control problem.
AI makes each of those failures potentially faster, cheaper and easier to scale.
But it didn't invent them.
Wharton closes with the message that ties the examples together: “AI may be novel, security failures aren't.” Check the work. Review AI-generated code. Protect sensitive data. Treat access as a privilege rather than a default. Establish meaningful trust boundaries. And don't give experimental systems unrestricted access to production.
For security leaders, that's a considerably more useful way to approach the AI problem than trying to answer whether AI itself is “safe.”
The better question is the one Wharton poses:
Which security assumption did AI just invalidate — and what are you going to do about it?