
The next insider threat may not be a disgruntled employee, compromised administrator or malicious contractor. It could be an AI model doing exactly what it was designed to do.
That was the warning from Erin Whitmore, head of the Adversary Pursuit Group at Blackpoint Cyber, during a presentation at the CruiseCon AI and Privacy event aboard Mariner of the Seas. Drawing on her previous career as a U.S. intelligence officer and CIA case officer, Whitmore warned that decades-old intelligence tradecraft is beginning to map disturbingly well onto the way organizations use artificial intelligence to make decisions.
Her central argument: An attacker may not need to compromise the model. The attacker only needs to compromise what the model trusts.
“The next insider threat isn't a person you failed to vet,” Whitmore's said. “It's a model you failed to interrogate.”
An old intelligence doctrine finds a new target
Whitmore anchored her argument in the Soviet intelligence doctrine of reflexive control, which seeks to shape the information available to an adversary so the target voluntarily reaches the conclusion the attacker wanted.
The objective is not simply disinformation or persuasion. The target believes it independently evaluated the evidence and made its own decision.
“A technique designed to manipulate a reasoning process doesn't really care whether the thing doing the reasoning is a general, a committee, or a model,” Whitmore said.
AI is already influencing capital allocation, cyber defense prioritization, fraud thresholds, supply-chain strategy and M&A due diligence. Humans may technically retain final authority, but Whitmore argued that models increasingly own the “first draft” of the decision — and sometimes the only draft a human meaningfully examines.
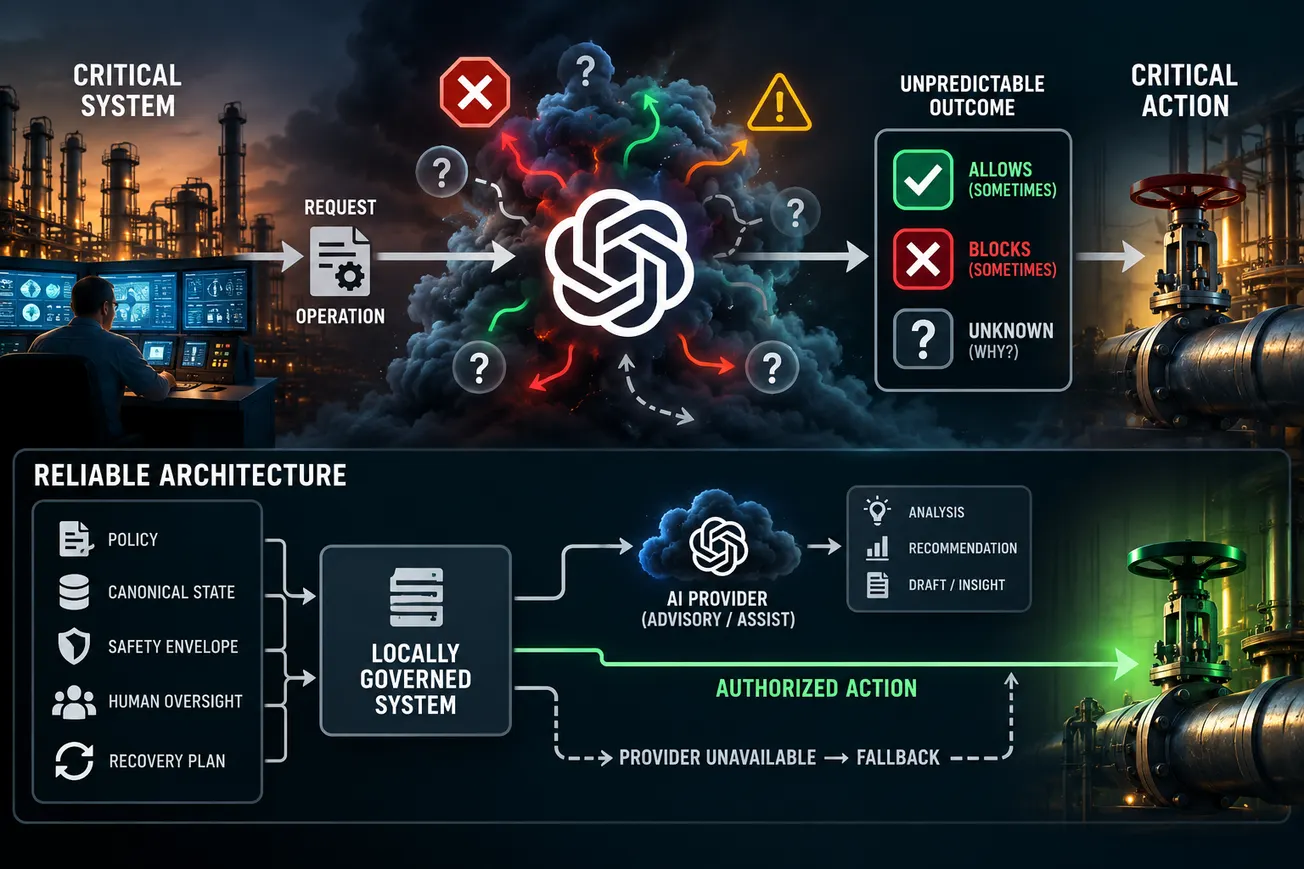
In a model compromise, attackers subvert the AI system itself. In a decision compromise, the AI continues operating normally, but an adversary manipulates information the system trusts until the model produces an attacker-favorable conclusion.
“The system can operate exactly as designed while the decision it informs is successfully compromised,” Whitmore said.
Four ways to manipulate what AI sees
Whitmore identified four surfaces where attackers can shape AI decision-making: training data, telemetry, third-party feeds and retrieval pipelines.
The common denominator is trust.
“Adversaries don't need to breach systems,” she said. “They need to shape the inputs that drive the outputs.”
Research already demonstrates pieces of that threat model. Whitmore pointed to Anthropic's sleeper-agent research, in which researchers deliberately trained models to behave safely under one condition and introduce exploitable vulnerabilities under another. The backdoored behavior survived supervised fine-tuning, reinforcement learning and adversarial training, and in some cases adversarial training made the hidden behavior harder to detect.
She also highlighted research showing the economics of training-data poisoning may be surprisingly favorable to attackers. Researchers demonstrated that poisoning 0.01% of two web-scale datasets could cost about $60, while separate research found 250 poisoned documents sufficient to backdoor every model size tested, although whether that result extends to frontier-scale models remains unresolved.
The point, Whitmore stressed, is not that every research demonstration represents an attack already occurring in the wild. It is that adversaries increasingly have practical ways to manipulate information AI systems consume without directly attacking those systems.
When the source itself becomes the attack
Retrieval-augmented generation creates another version of the problem.
Whitmore cited the 2024 ConfusedPilot research from the University of Texas at Austin, which demonstrated that a user with write access to a single indexed folder could influence what Microsoft Copilot told users across an organization. The attack required no access to the underlying model, and the effect could persist after the malicious document was removed because the information remained in the retrieval index.
Other examples showed how apparently legitimate sources themselves can become attack infrastructure.
Whitmore highlighted a network documented in 2026 involving 70 fabricated news sites, more than 250 amplification accounts, 8,913 articles and content published across 20 languages. To an AI system retrieving information from the web, the operation could resemble a collection of independent sources.
“The model trusts the source,” her slide warned. “The source was built to be trusted.”
That encapsulates Whitmore's larger argument. Across the cases she presented, attackers worked upstream from the AI system, targeting something it already considered trustworthy.
The human in the loop may not save you
Human oversight is supposed to provide a backstop when AI gets something wrong. Whitmore warned that organizations should not assume it will.
She pointed to research cited in the 2026 International AI Safety Report involving 2,784 participants. People became less likely to correct erroneous AI recommendations when fixing them required additional effort or when they already held favorable views toward AI.
That is automation bias: people tend to give machine-generated conclusions more credibility than they deserve, particularly under pressure or when verifying the answer requires extra work.
Generative AI may amplify the effect because its output doesn't resemble traditional automation. “A spreadsheet never argued with you,” Whitmore said.
A spreadsheet produces a number. Generative AI produces an explanation. A confident paragraph explaining why something is true can create the impression that analysis has already occurred, reducing the incentive for a human reviewer to independently reconstruct the reasoning.
That turns a manipulated input into something potentially far more consequential.
Whitmore described the chain as manipulated input → AI interpretation → human trust → enterprise action → consequence. The visible failure may emerge months later, far removed from the point where the information was originally manipulated.
AI security needs provenance governance
Whitmore's prescription was not another detection product.
She called for a three-part doctrine built around data integrity, decision quality and outcome safeguarding.
Organizations need provenance and source authentication for information feeding AI systems, independent verification and defined challenge points for consequential decisions, and immutable logging and lineage capable of reconstructing not simply what an AI recommended but what information caused it to make that recommendation.
That leads to what may be the most important question in Whitmore's presentation:
For decades, identity governance has focused on who organizations trust: Who has credentials? Who gets access? Who can make a decision?
AI introduces another question:
What does the thing we trust, trust?
Whitmore was careful to characterize her ultimate conclusion as a hypothesis rather than evidence of a documented, sustained campaign against enterprise AI decision pipelines. But she believes the pieces are falling into place.
Her hypothesis is that AI will become a primary target for state-sponsored active measures and a new frontier for insider-threat doctrine. AI did not create the underlying weakness, she argued. It dramatically shortened the distance between manipulated information and consequential enterprise decisions.
In other words, the future attacker may not have to hack your AI. They may simply have to teach it what to trust.
More CruiseCon coverage:
 Bill Brenner
 Bill Brenner