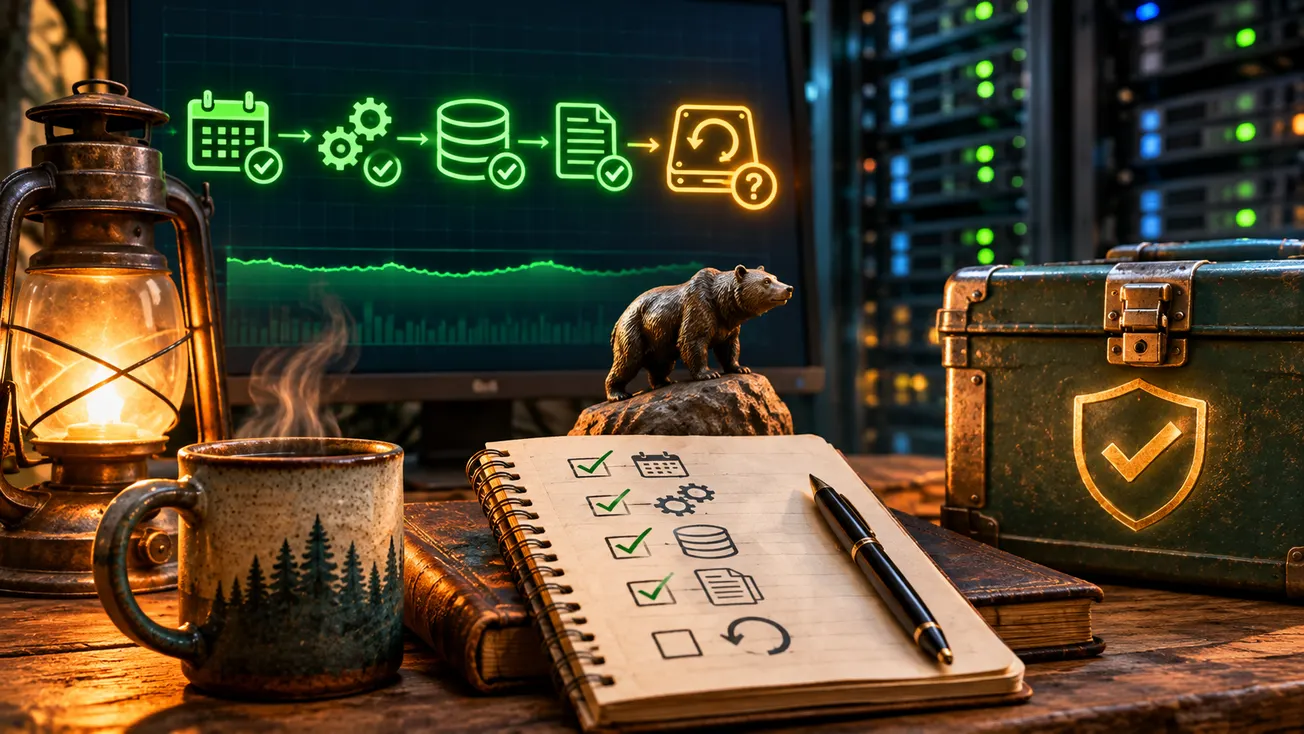
The backup timer was green.
More precisely, it was active, which in the wonderfully literal world of computers is often what we have chosen to mean by green. The timer existed. It was enabled. It was doing its best to wake up periodically and arrange for a backup to happen.
The backup itself wasn't happening.
There is a lesson in that distinction, although it is not quite the lesson people sometimes expect. This is not an article about how foolish it is to trust a dashboard, or how AI is about to rescue us from unreliable computers. It is about a much older problem: we keep measuring whether the machinery is doing what we told it to do, and confusing that with whether the machinery is doing what we needed it to do.
Recently, while working through the health of a small mesh of systems we operate, we noticed that part of the backup infrastructure was not well. The management agents were present. The network was generally alive. Backup timers were active. And the backup jobs had been recording timeouts.
One of the underlying file services had been down for about a month.
I have spent enough of my life around security infrastructure to find that both irritating and familiar. There is something almost affectionate about the way a complex system can keep carrying out its individual responsibilities while the thing those responsibilities are supposed to accomplish quietly fails. Everybody has turned up for work. Nobody has noticed that the building is missing.
Except that isn't entirely fair. The errors were there. A service had failed. Jobs had timed out. The evidence existed, distributed among machines and logs and different views of the same storage.
What was missing was a reliable way to connect those observations to the responsibility that mattered.
We weren't trying to maintain a collection of green timers. We were trying to preserve information so that somebody could recover it when something went wrong.
Those are not remotely the same job.
There were several useful false leads along the way. One inspection showed a storage path as read-only, which is an excellent way to persuade an operator that a disk has developed an exciting and expensive personality. But when we compared the ordinary agent's constrained view with the host's actual mount state, the host filesystem was read-write. The agent was supposed to see a restricted view. That was an authority boundary functioning correctly, not evidence that the disk had failed.
On another machine, the backup directory appeared to be mounted. It had a familiar path. It was present in the mount table. All very reassuring, until we distinguished the automount mechanism from an actual, working network filesystem behind it. A placeholder that promises to arrange a mount when somebody needs one is not the same thing as a client that has successfully mounted remote storage.
Nothing about either observation was necessarily false. Each was true within the particular context of the observer. The error came when one kind of truth was promoted into another.
Then the clocks gave us the useful clue.
The file service had tried to bind to an address on a private mesh network. At boot, the ordinary network-ready milestone had been reached, but the mesh interface hadn't yet finished making that address available. The file service tried to start and received the rather unromantic equivalent of that address does not exist here. Nine seconds later the mesh interface was ready.
Nine seconds.
The system was, by then, perfectly capable of talking to the rest of the mesh. Its backup service had already failed and remained failed. The later arrival of the network did not go back in time and make the earlier startup successful.
This was not a spectacular vulnerability. Nobody had defeated encryption, escaped a sandbox or convinced a language model to turn evil. It was a dependency that existed in the actual world but was inadequately represented in the startup sequence. The system that needed a particular network identity had been told, in effect, that the network was ready before that identity existed.
The repair was correspondingly unglamorous. We checked the actual configuration, the service failure, the host filesystem and the intended export boundaries. We made a narrowly scoped correction to the service dependency and binding behavior, preserving the network restrictions rather than making the service listen everywhere. The responsible human approved and ran the host-level change. Then we checked the result independently from the client machines.
The service was listening again. The clients could reach it. More importantly, we made them prove that their network filesystems were real and usable, rather than merely trusting the existence of a directory where the filesystem ought to be.
No grand autonomous healing ceremony. No invitation for an AI assistant to acquire unrestricted administrative privileges because a machine was being awkward. A bounded change, a reason for that change, and observations of the world afterward.
That last part matters more than it looks.
It's very easy to write a clever script that returns success. It is harder to decide what success means outside the script.
By the next day, the two backup services we had been watching were completing with successful exit statuses. That was a genuine improvement over the earlier timeouts. The transport and mount dependencies had been repaired, and the scheduled work was able to finish.
We had restored something important.
We had not yet proved everything the word backup implies.
A job exiting successfully tells us something about the job. It does not, by itself, establish that the resulting artifacts contain all the intended data, that their checksums match independent source evidence, that the newest copy is sufficiently fresh, that retention is appropriate, that the relevant people have access to the necessary recovery information, or that someone can actually restore the system without the original operator standing beside them remembering a mysterious exception from last Thursday.
That final question is the one I would like more security dashboards to ask.
Not did the backup process run?
Not even did it write something to another machine?
What can we demonstrably recover, from which point in time, and how do we know?
A checksum can help us establish that bytes survived a journey unchanged. It cannot tell us whether we backed up the right bytes. A successful file copy does not certify the consistency of a database snapshot. A restorable little test file is useful evidence, but it is not a substitute for demonstrating that an application and its dependencies can be reconstructed. An impressive disaster-recovery runbook is not evidence that anyone has successfully followed it since the person who wrote it moved to another department.
Every layer answers a different question. A healthy system keeps those questions separate long enough to answer them properly.
This becomes particularly interesting when we introduce AI into operations. One of the things these systems can genuinely help with is connecting evidence that humans would otherwise have to gather by hand. They can compare logs from several machines, notice a nine-second ordering problem, identify a misleading namespace boundary, draft a constrained repair, and propose tests that can be independently checked.
That is useful. I would like a great deal more of it.
But a model's ability to tell a coherent story about the incident is not the same as the authority to repair it, and neither is the same as proof that the organization's obligation has been met. A model can describe the right dependency and still be operating with stale information. It can report that a command returned zero without knowing what the command actually changed. It can produce a plausible recovery narrative without possessing a single recoverable byte.
The better the language gets, the easier it is to confuse those levels.
So I don't want my AI operator to tell me simply that the backup is healthy. I want it to tell me what it observed, when it observed it, which machine or identity supplied the evidence, which part of the process was tested, and where the evidence stops. I want it to be able to say that the mount is fixed but restoration remains unproven. I want it to be comfortable with an incomplete answer when an incomplete answer is what the world currently supports.
I want the system to preserve a failure as a failure until the thing that failed has actually been made whole.
This is an important difference between monitoring components and governing responsibilities. The first asks whether pieces are working. The second asks whether the institution can still do what those pieces exist to make possible.
Backups are a particularly good place to discover the difference because they make a promise about the future. If something breaks, if a machine is lost, if somebody makes an ugly mistake, if the only person who understood the arrangement happens to be on a plane, there should be a way back.
A backup is not merely yesterday's process. It is tomorrow's option.
If I were redesigning that green indicator, I might replace it with something less cheerful and considerably more useful: the last independently verified recovery point, its age, the source and destination that were checked, the type of restoration actually attempted, and the remaining uncertainties. Some of those fields might be empty. Empty would be an honest condition, and therefore a place to begin work.
There is no reason to make this complicated for the people depending on it. A simple green indicator can still be useful, provided it is green for the right proposition. If its meaning is “the scheduler is active,” label it that way. If its meaning is “the last scheduled job exited successfully,” say that. And if it says “recovery ready,” somebody ought to be able to show you a recovery.
We have repaired the failed storage dependency in our own mesh and watched the backup processes return to successful completion. The next obligation is to establish a fresh, independently checked recovery artifact and restore a safe fixture without disturbing live data. Later comes the harder exercise of demonstrating useful recovery under real disruption, ideally by somebody who did not design the entire arrangement.
Until those gates are met, I am not going to call the durability problem finished merely because the timer has become pleasant to look at again.
The machines have given us enough little green lights. What we need now is evidence that the world on the other side of those lights is still there.
And that we can get it back.
-chris