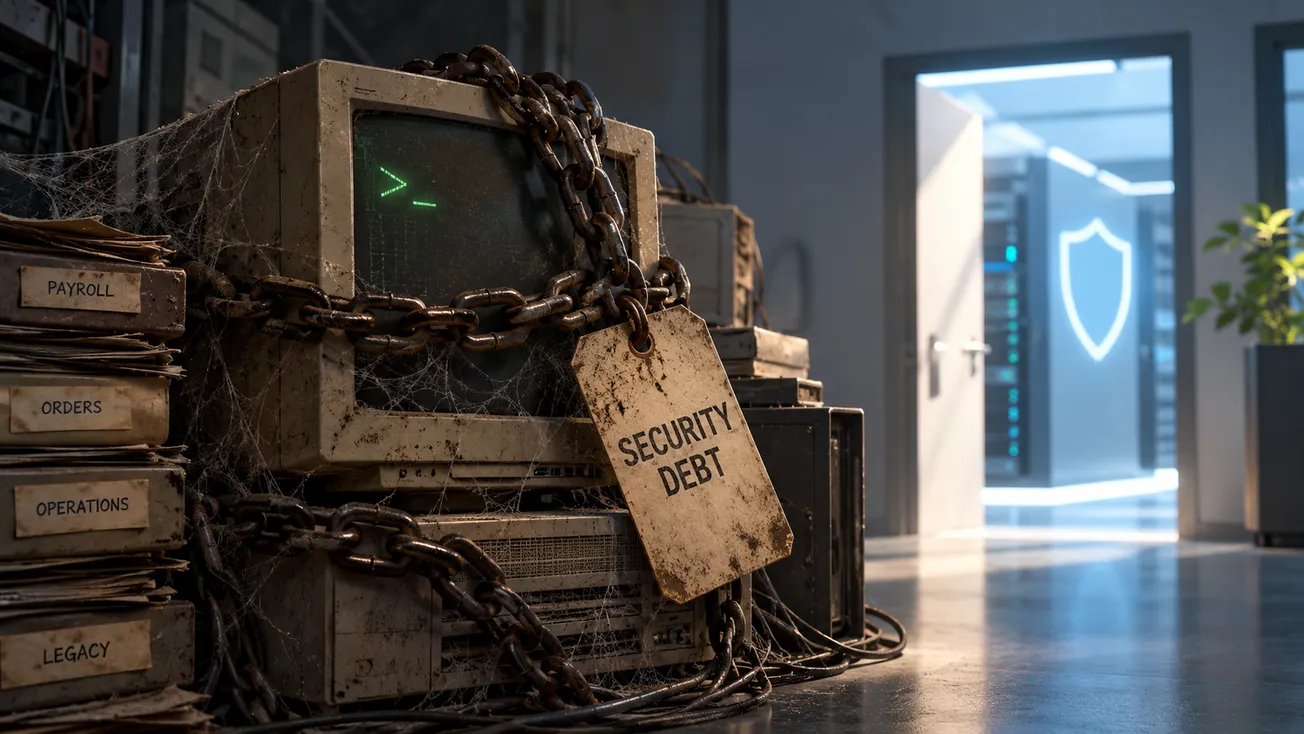
What is security debt? Simply put it is the accumulation of security risk created by decisions that were convenient at the time and expensive to fix later. The only problem is that later never comes and the debt compounds.
Legacy systems are one of the clearest examples. They stay in place because they still run payroll, process orders, connect to factory equipment, or support some workflow nobody wants to break. The business keeps moving. The debt keeps growing.
That is what makes legacy systems dangerous. The problem is rarely a single outdated server or an old application sitting in a corner. The problem is that these systems often become untouchable. Nobody wants to patch them. Few people understand them well enough to change them. Every integration around them gets built with compromise in mind. Over time, the organization stops managing the risk and starts accommodating it.
A lot of security teams inherit this situation and respond with the wrong question: how do we secure the legacy system? That matters, but it is not the first question. The first question is why the system still has so much power over the environment. If an old platform can force weak authentication, delay patching cycles, preserve old network paths, and block logging improvements, then the issue is broader than one aging asset. The system has become a source of architectural drag.
Legacy systems create security debt in predictable ways.
First, they preserve outdated trust assumptions. Older platforms were often designed for internal networks, smaller user populations, and less hostile traffic. They assumed that being inside the perimeter meant being safe. That assumption is dead. Once a legacy system requires flat network access, shared service accounts, broad administrator rights, or exceptions to segmentation policy, it starts weakening everything around it.
Second, they interrupt normal patch and hardening practices. Some systems are tied to software versions that cannot move without breaking an application. Others depend on vendors that only certify changes twice a year, if that. In many environments, “compensating control” becomes a polite way of saying “we gave up on fixing the root problem.” Extra monitoring helps.
Firewall rules help. Virtual patching helps. None of those erase the fact that the vulnerable component is still there, still exposed to whatever reaches it.
Third, they create blind spots. Modern security programs rely on telemetry, identity signals, asset inventory, vulnerability coverage, and centralized logs. Legacy systems often do not integrate cleanly with any of that. They may not support modern endpoint tooling. They may generate logs in formats nobody collects. They may authenticate through old protocols that hide who did what. A system you cannot see clearly is a system you will defend badly.This is why legacy risk is usually underestimated by leadership. On paper, the system is stable.
It has been running for years. There have been no obvious incidents. Revenue still flows through it. That can look like reliability. In security terms, it often means prolonged exposure with limited visibility. The absence of a known breach is weak evidence. It may simply mean no one was in a position to detect one.
Another mistake is treating legacy systems as a technology age problem. Age matters, but age alone is not the issue. The real risk comes from dependency and exposure. An old system that is isolated, monitored, tightly controlled, and functionally contained may be manageable. A newer system that forces insecure workarounds can be worse. What matters is the path of compromise. Can the asset be reached from the internet, from user workstations, from third parties, or from shared admin networks? Can it authenticate against modern identity systems?
Does it hold sensitive data? Does it control a critical process? Can you recover if it fails? Those answers tell you more than the release date.
This is also where security debt becomes a business problem. Legacy systems consume attention. They slow down control adoption. They increase exception handling. They turn routine audits into negotiation. They force engineers to spend time maintaining fragile compatibility instead of reducing risk. The cost is not abstract. It shows up in longer remediation timelines, narrower design choices, and a higher chance that one compromised box becomes a much larger incident.
The right response is not a dramatic “rip and replace” slogan. Most organizations cannot do that, and many should not try. The right response is to reduce the blast radius while building an exit path.
Start with ownership. Every legacy system needs a named business owner and a named technical owner. If ownership is vague, risk decisions will also be vague.
Next, map dependencies. Identify what the system talks to, what talks to it, who administers it, what data it stores, and what breaks if it goes offline. Many teams skip this step because it feels operational. It is actually core security work. You cannot reduce the risk of a legacy platform if you do not know what depends on it.
Then limit trust. Segment the system aggressively. Remove direct internet exposure if it exists.
Restrict administrative access. Eliminate shared credentials where possible. Put modern authentication in front of the system, even if the system itself cannot support it. Collect whatever logs you can and monitor the choke points around it.
After that, make the replacement real. Not aspirational, real. Set a date for support review. Fund the migration work. Tie reduction goals to business planning, not just the security roadmap.
Legacy debt survives when everyone agrees it is a problem and nobody changes the budget.
If you are leading security, the practical move this week is simple. Build a list of every production system that cannot support your current baseline for patching, logging, MFA, or endpoint controls. For each one, record the owner, the business function, the network exposure, and the planned retirement date. Then pick the single highest-risk system on that list and do one concrete thing in the next 30 days: remove internet access, place it behind a controlled access layer, or cut off an unnecessary trust relationship. That is how security debt starts to shrink, one forced compromise at a time.
In the next post in this series, I’ll cover the second major source of security debt, exception culture, and how “temporary” workarounds become permanent attack paths.